the lab_id column of the Strucke Data gives both the name of the lab, and the number that lab used to identify the sample.
Bruno used AI to extract the 54 lab name abbreviation from the lab_id to extracted_lab_prefix, and then manually edited some of the resulting list in the manual_prefix column
- figure out the best way to record the information that Beta/CAMS, Beta/ETH, and Beta/AMS all had their pre-processing done at Beta, and the dating done at the lab in the second half of the name (in the short term, I just copied these terms into the manual_prefix column)
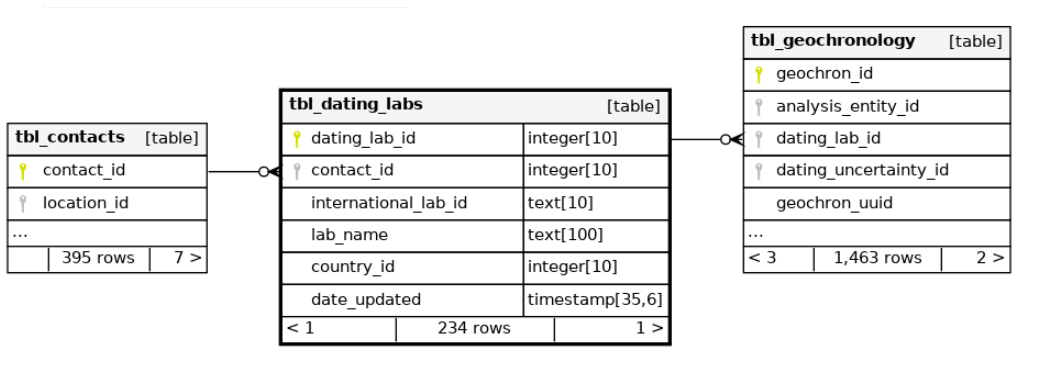
YAML as of 2026-09-29
name: dating_lab
type: fixed
system_id: system_id
keys: []
columns:
  - system_id
  - dating_lab_id
  - extracted_lab_prefix
  - manual_prefix
public_id: dating_lab_id
values: '@load:materialized/dating_labs.parquet'
materialized:
  enabled: true
  source_state:
    type: csv
    keys: []
    columns:
      - extracted_lab_prefix
      - manual_prefix
    public_id: dating_lab_id
    options:
      filename: /app/projects/Bruno-Strucke-v2-Raw-dataset/extracted_lab_prefix_map.csv
      sep: ','
      encoding: utf-8
  materialized_at: '2026-09-10T06:52:07.348439'
extra_columns:
  lab_name: '{manual_prefix}'

```