- I think we should also add a modification_type_description, do the others agree?
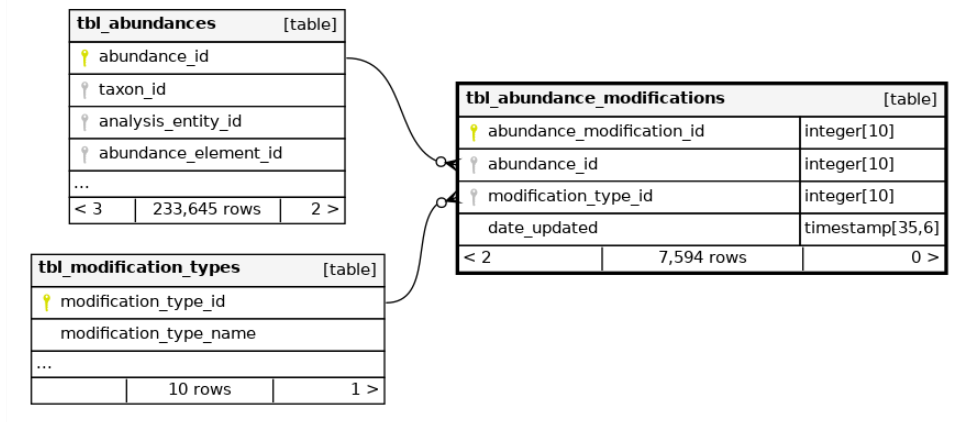
The "material" column of the Strucke data sometimes has additional information in the cell which would fall under tbl_abundance_modifications:
- (ej förkolnat)
- brända
- obrända
- obränt
this information will need to be extracted from this column before data ingestion. None of these are already in SEAD (see tbl_modification_types), so they will all get new modification_type_id as well as abundance_modification_id numbers
- create a fixed-values entity for modification types
- add columns for modification_type_name and modification_type_description
- fill in the fixed values for them as follows:
| modification_type_id | modification_type_name | modification_type_description |
|---|---|---|
| brända | used when the material analysed was burned | |
| obrända | used when the material analysed was not burned (presumably noted as such because most material in that project was) | |
| obränt | used when the material analysed was not burned (presumably noted as such because most material in that project was) | |
| förkolnat | used when the material analysed was charred | |
| ej förkolnat | used when the material analysed is not charred (presumably noted as such because most material in that project was) |
YAML as of 2026-09-21
name: modification_type
type: entity
system_id: system_id
keys: []
columns:
  - modification_type
public_id: modification_type_id
source: superabundance
drop_duplicates: true
check_functional_dependency: false
drop_empty_rows: true
```